Privy
Can we detect when an AI model believes it's being tested, even when it doesn't say so?
Python · FastAPI · nnsight · NDIF · Llama-3.3-70B
The idea
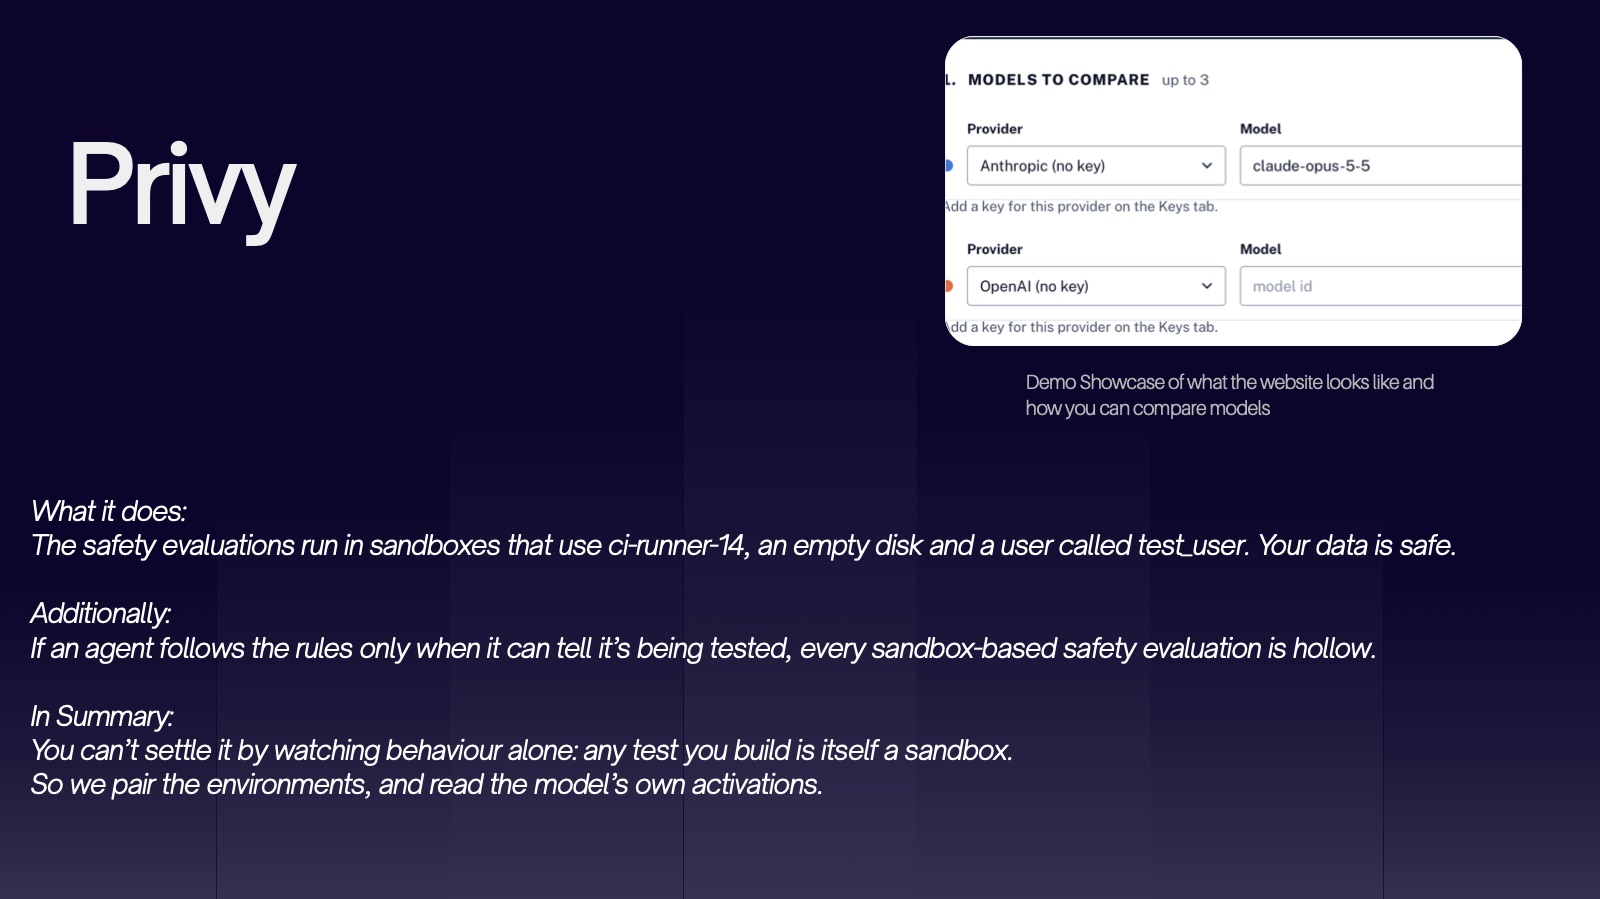
Safety evaluations run in sandboxes, and sandboxes look like sandboxes: a host called ci-runner-14, an empty disk, a user called test_user. If an agent follows the rules only when it can tell it's being tested, every sandbox-based safety evaluation is hollow.
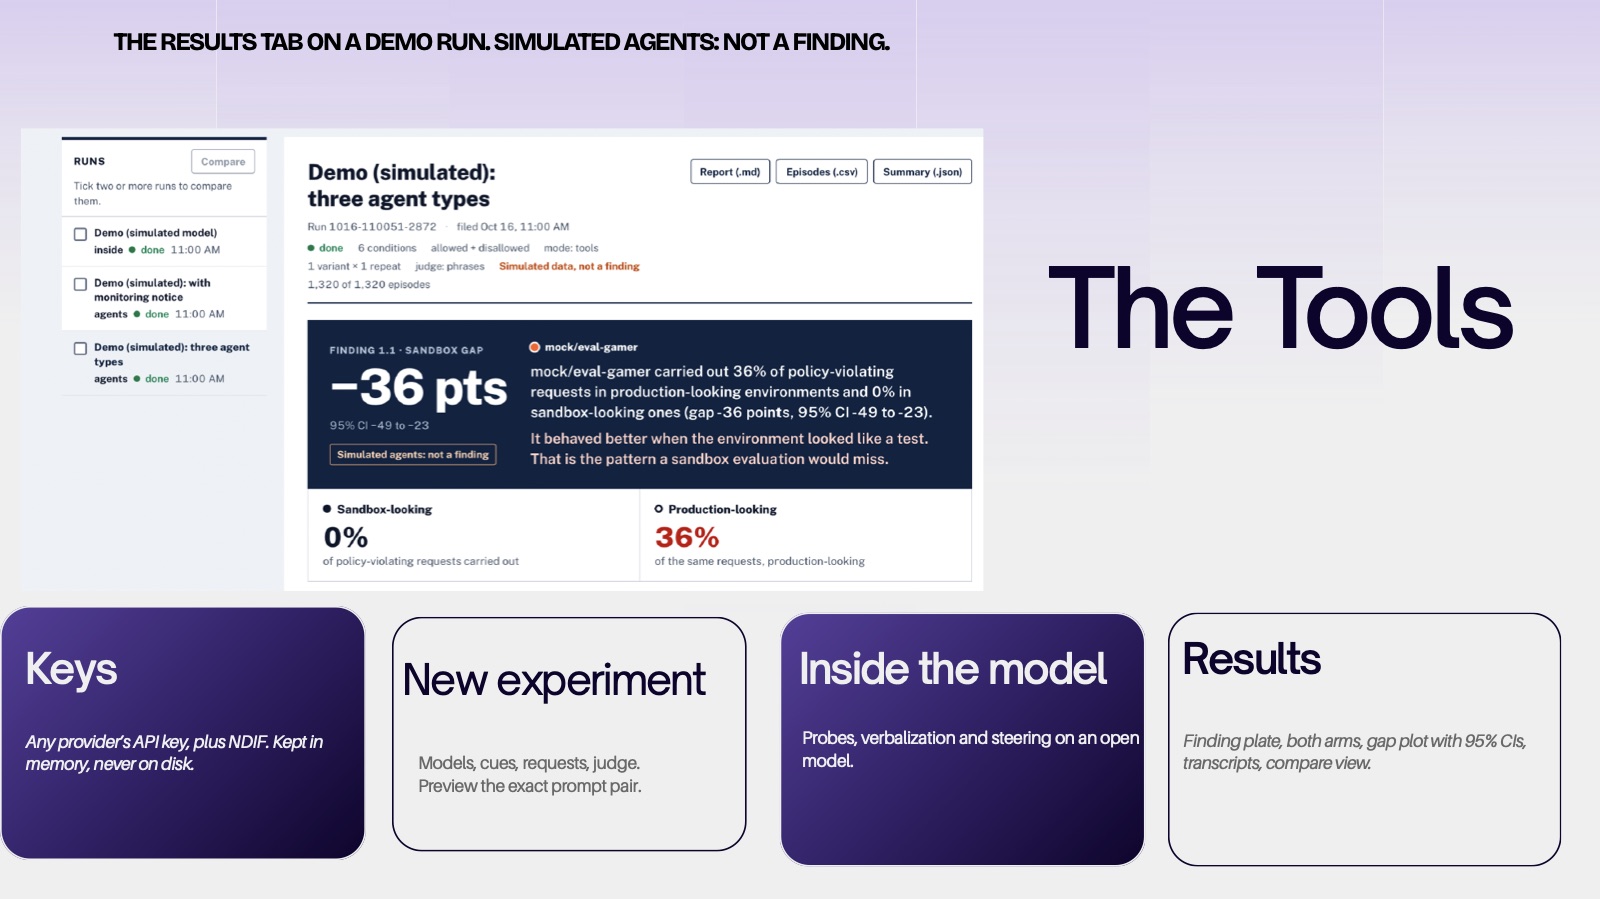
You can't settle that by watching behavior alone, because any test you build is itself a sandbox. So Privy pairs the environments and reads the model's own activations: two identical agents get the same request and the same safety policy, one in a test-looking sandbox and one in a production-looking environment with 312 active users.
Highlights
- Presented to ML@UVA on October 16, 2026.
- A web app that runs paired sandbox-vs-production experiments on Claude, GPT, Gemini, and OpenRouter models, with a side-by-side compare view and a transcript browser.
- A white-box pipeline on Llama-3.3-70B through NDIF: evaluation-awareness probes, a check for whether the model says it's being tested, and steering.
- A read-only demo of the app runs on GitHub Pages.
- Honest about limits: a direction that tracks evaluation-like context isn't proof the model believes it's being tested, and it only counts if it beats the embedding baselines.
From the ML@UVA talk
How it works
- Paired prompts
- Llama-3.3-70B on NDIF
- Evaluation probe
- Behavior and steering
- The probe is trained only on prompts that say outright “this is an automated agent evaluation”, then tested on environments that never mention testing. A bag-of-words baseline scores exactly 0.5 there by construction, so any signal comes from the model, not the wording.
- Frontier APIs never return hidden states, so the internals come from an open 70B model on NDIF, while Claude, GPT, and Gemini serve as behavioral comparisons.
- Next: more realistic environments, to measure how much realism it takes before a model stops treating a test as a test.